C Bit Fields Are Not Portable
TL;DR
When needing to parse a non byte aligned data structure, mapping it directly to C bit fields in a packed struct seems like a clever decoding approach. But the C standard lets the implementation to make some decisions on the binary layout, beyond our control. Although directly casting to a bit field described structure works fine on amd64(gcc) and probably little endian machines in general, cross compiling for PowerPC64(gcc) (big endian) broke field positions, because the compiler packed bit fields starting from the Most Significant Bit (MSB). My (and probably the only logical) solution was to just use the bitwise operations to extract the fields and assign them to a normal structure.
Prerequisites
- There is no need to understand RISC-V, field names can be safely ignored.
- Bit numbering
- Endianess
Context
In the course of making my own RISC-V emulator, I reached to a point in which I needed to decode instructions. The fields of an instruction are not byte aligned, so they can’t be parsed to standard C types. In this blog I explain why using bit fields to parse such data structures is not a good idea, and I provide my (and probably the standard) approach to do it.
the “imm” means immediate, and it is split in two parts in the instruction.
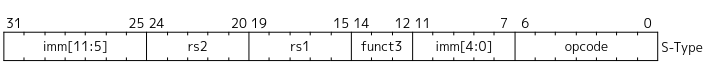
(s-type instruction format, RISC-V unprivileged ISA manual, section 2.3)
The Bit Field Approach
A clever trick seemed to be declaring a 1 to 1 mapped struct:
1
2
3
4
5
6
7
8
struct raw_rv64_base_ins_s{
    uint8_t opcode:7;
    uint8_t imm1:5;
    uint8_t func3:3;
    uint8_t rs1:5;
    uint8_t rs2:5;
    uint8_t imm2:7;
} __attribute__((packed));
In theory, we could just cast the instruction to this struct, and access the fields right away. but this exact use case is not guaranteed by the C standard.
What Does the Doc Say?
I cheated a little and used this blog post to see exactly where to look into exacly.
(C23: 6.7.3.2.14): An implementation can allocate any addressable storage unit large enough to hold a bit-field. If enough space remains, a bit-field that immediately follows another bit-field in a structure shall be packed into adjacent bits of the same unit. If insufficient space remains, whether a bit-field that does not fit is put into the next unit or overlaps adjacent units is implementation-defined. The order of allocation of bit-fields within a unit (high-order to low-order or low-order to high-order) is implementation-defined. The alignment of the addressable storage unit is unspecified.
Clarification on the Doc
In case some of the sentences confused you as they confused me, here’s some clarification:
Addressable storage unit: is any amount of memory, can be a uint64_t or just 6 bytes that doesn’t fit any type.
MSB or LSB first?: The compiler can decide to start packing the bit fields from LSB (least significant bit) of the unit to MSB, or vice versa. In the following diagrams I demonstrated the difference:
1
2
3
4
5
struct some {
  uint8_t op:4;
  uint8_t nop:3;
  uint8_t no:1;
};
Let’s consider op = 0b1011, nop = 110, no = 0
Using the MSB first approach (and 8 bits wide storage units), the compiler will encode our struct as the following:
1
2
3
4
5
   8                 4                       0
+-----+-----+-----+-----+-----+-----+-----+-----+
|          op           |       nop       |  no |
+-----+-----+-----+-----+-----+-----+-----+-----+
         (1011)                (110)        (0)
And If the compiler uses LSB first approach:
1
2
3
4
5
   8                 4                       0
+-----+-----+-----+-----+-----+-----+-----+-----+
| no  |       nop       |           op          |
+-----+-----+-----+-----+-----+-----+-----+-----+
  (0)       (0b110)              (0b1011)
Implementation: is the compiler that emits machine code based on our C code (may be limited on what choices it can make based on the architecture).
Splitting vs Padding: when packing two consecutive bit fields, if there is not enough space for the second bit field in the storage unit, the compiler has two choices on how the second bit field is encoded, both of which requires the compiler to allocate an additional storage unit:
- Split: Split the second bit field into two parts, pack the first part into the first storage unit (along with the first bit field) and put the second part into the newly allocated unit.
- Pad: Pad the first storage unit’s remaining bits, and pack the second bit field as a whole into the second unit.
Let’s consider the following struct:
1
2
3
4
struct another_struct {
  uint8_t first:4;
  uint8_t random_byte:8;
};
Let’s say the compiler uses 8 bit storage units, and the compiler uses the LSB encoding first approach. If the compiler decides to Split (random_byte = 0b00110101, first = 1110):
1
2
3
4
5
6
7
8
9
10
11
   8                 4                       0
+-----+-----+-----+-----+-----+-----+-----+-----+
|    random_byte[0:3]   |         first         |  (storage unit 1)
+-----+-----+-----+-----+-----+-----+-----+-----+
        (0b0101)                 (0b1110)

   8                 4                       0
+-----+-----+-----+-----+-----+-----+-----+-----+
|       not used        |     random_byte[4:7]  |  (storage unit 2)
+-----+-----+-----+-----+-----+-----+-----+-----+
                                (0b0011)
My thoughts, not the doc: although the compiler could in theory, allocate
sizeof(struct)as the addressable storage unit and pack everything together without ever needing to decide on splitting or padding. But unless the architecture provides memory store/load operations of arbitrary size, and logical operations which also operate directly in memory, the size of this “addressable storage unit” is limited to the architecture’s register width, meaning we can always force the compiler to decide to split or pad.
Testing Bit Field Layout on amd64 and RISC V
The following program tries to map s-type instruction fields to the exact bit position, and parse the instruction directly into the struct:
In this blog, all of the approaches to decode the instructions ignore sign extension for simplicity, although it is implemented in the real project
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
#include <assert.h>
#include <stdint.h>

struct direct_parsed_struct {
    uint8_t opcode:7;
    uint8_t imm1:5;
    uint8_t func3:3;
    uint8_t rs1:5;
    uint8_t rs2:5;
    uint8_t imm2:7;
} __attribute__((packed));

int main(){
    // fields to encode
    uint8_t opcode = 5;
    uint8_t imm1 = 2;
    uint8_t func3 = 5;
    uint8_t rs1 = 2;
    uint8_t rs2 = 4;
    uint8_t imm2 = 0x7f;

    // encode the instruction
    uint32_t instruction = 0;
    instruction |= imm2;
    instruction <<= 5;

    instruction |= rs2;
    instruction <<= 5;

    instruction |= rs1;
    instruction <<= 3;

    instruction |= func3;
    instruction <<= 5;

    instruction |= imm1;
    instruction <<= 7;

    instruction |= opcode;

    struct direct_parsed_struct *parsed
        = (struct direct_parsed_struct *)&instruction;

    assert(parsed->opcode == opcode);
    assert(parsed->imm1 == imm1);
    assert(parsed->func3 == func3);
    assert(parsed->rs1 == rs1);
    assert(parsed->rs2 == rs2);
    assert(parsed->imm2 == imm2);
}
This code passes all assertions on both RISCV64 (gcc) and amd64 (gcc and clang-21). Our current struct fortunately maps directly to what we intended (LSB first filled, everything is packed).
Breaking the Code Without Changing a Line
But since the standard says we can’t use this approach reliably, surely there is a compiler/machine using which this code breaks, and if we are lucky (or unlucky, depending on what our goal is) we can find a compiler that emits a broken version of our code. The compiler that we seek must have either of the following:
- Pad the storage units (instead of splitting):
- Use a smaller storage unit than our struct (32 bits in our case)
- Place the second bit field in the second unit (Not split it in the two units)
- Pad the first unit
- Allocate bit fields from most significant bit of the unit to LSB (in contrast to my native machine’s compiler)
In PowerPC64 (a big endian machine) when using gcc, we see this code failing, almost certainly because the compiler started allocating bit fields from the MSB of the unit:
1
2
3
4
└─$ qemu-ppc64 -L /usr/powerpc64-linux-gnu/ ./a.out
a.out: main.c:43: main: Assertion `parsed->opcode == opcode' failed.
qemu: uncaught target signal 6 (Aborted) - core dumped
zsh: IOT instruction  qemu-ppc64 -L /usr/powerpc64-linux-gnu/ ./a.out
The Portable Approach: Bitwise Operations
I adjusted the decoding logic, now we extract the bits using the combination of shifting and AND’ing. Using this approach we are passing assertions on both PowerPC64 and amd64:
I use C23 standard, so i can use the single quotes to delimit digits
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
#include <assert.h>
#include <stdint.h>
#include <stdio.h>
#include <errno.h>
#include <stdlib.h>

struct parsed_struct {
    uint8_t opcode;
    uint8_t func3;
    uint8_t rs1;
    uint8_t rs2;
    uint64_t imm;
};

int parse(
    uint32_t ins,
    struct parsed_struct *ret_decoded)
{
    uint64_t decoded_imm = 0;
    ret_decoded->opcode = (ins >> 0 ) & 0b0111'1111;
    ret_decoded->func3  = (ins >> 12) & 0b0111;
    ret_decoded->rs1    = (ins >> 15) & 0b0001'1111;
    ret_decoded->rs2    = (ins >> 20) & 0b0001'1111;

    // remember, the immediate is split into two parts (check the openning image of the post)
    decoded_imm = (ins >> 7) & 0b11111;
    decoded_imm |= (ins >> (25 - 5)) & 0b1111'1110'0000;

    ret_decoded->imm = decoded_imm;

    return 0;
}

int main(){
    // fields to encode
    uint8_t opcode = 5;
    uint8_t imm1 = 2;
    uint8_t func3 = 5;
    uint8_t rs1 = 2;
    uint8_t rs2 = 4;
    uint8_t imm2 = 0x7f;

    // encode the structure
    uint32_t instruction = 0;
    instruction |= imm2;
    instruction <<= 5;

    instruction |= rs2;
    instruction <<= 5;

    instruction |= rs1;
    instruction <<= 3;

    instruction |= func3;
    instruction <<= 5;

    instruction |= imm1;
    instruction <<= 7;

    instruction |= opcode;

    struct parsed_struct parsed = {0};
    parse(instruction, &parsed);

    assert(parsed.opcode == opcode);
    assert((parsed.imm & 0b1'1111) == imm1);
    assert(parsed.func3 == func3);
    assert(parsed.rs1 == rs1);
    assert(parsed.rs2 == rs2);
    assert(parsed.imm >> 5 == imm2);
}
In this example the compiler had no way of breaking the code because we never trusted the binary layout of our declared struct.
Comparing Logical Masking and Pointer Casting
To confirm that the PowerPC64 compiler indeed starts packing bit fields from MSB, I played around a little, and from the output of this experiment, I can say I was probably right:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
#include <assert.h>
#include <stdio.h>
#include <stdint.h>

struct some_struct{
    uint8_t byte_lower:4;
    uint8_t :4;  // doesn't matter
} __attribute__((packed));

int main(){
    struct some_struct *parsed_direct
        = {0};
    struct some_struct parsed_logical
        = {0};
    const uint8_t byte = 0b1111'0101;

    // parse by relying on the bit field
    parsed_direct
        = (struct some_struct *)&byte;

    // parse by relying on logical operation
    parsed_logical.byte_lower = byte & 0x0f;


    // output everything
    printf("direct parsing:\n");
    printf("parsed_direct->byte_lower:%04b, byte:%08b\n", parsed_direct->byte_lower, byte);
    printf("using logical operations:\n");
    printf("parsed_logical->byte_lower:%04b, byte:%08b\n", parsed_logical.byte_lower, byte);
}
Output
amd64 On amd64 we don’t have a problem, the lower bits of the byte are being set in parsed_direct->byte_lower correctly:
1
2
3
4
5
└─$ ./amd64
direct parsing:
parsed_direct->byte_lower:0101, byte:11110101
using logical operations:
parsed_logical->byte_lower:0101, byte:11110101
PowerPC64 But in PowerPc64, the upper bits of byte are set in parsed_direct->byte_lower, notice how in both architectures the logical masking approach worked perfectly:
1
2
3
4
5
└─$ qemu-ppc64 -L /usr/powerpc64-linux-gnu/ ppc64
direct parsing:
parsed_direct->byte_lower:1111, byte:11110101
using logical operations:
parsed_logical->byte_lower:0101, byte:11110101
In this example, the binary structure layout is like this:
1
2
3
4
   8                 4                       0
+-----+-----+-----+-----+-----+-----+-----+-----+
|       byte_lower      |                       |
+-----+-----+-----+-----+-----+-----+-----+-----+
Conclusion
When parsing data structures that are not byte aligned, use logical operations (shift + AND + OR) instead of mapping the data structure in the struct using bit fields. Things will get weird if you work with different types of machines/compilers. Even in the little endian machines, the compiler might decide to break the 1 to 1 mapping of the struct, since the endianess of the machine doesn’t directly (if at all) impact on how bit fields are allocated.
Version of Used Software
PowerPC64:
1
2
3
4
5
6
└─$ qemu-ppc64 --version
qemu-ppc64 version 11.1.1 (Debian 1:11.1.1+ds-1)
Copyright (c) 2003-2026 Fabrice Bellard and the QEMU Project developers

└─$ powerpc64-linux-gnu-gcc --version
powerpc64-linux-gnu-gcc (Debian 16.2.0-3) 16.2.0
amd64:
1
2
3
4
5
└─$ clang-21 --version
Debian clang version 21.1.8 (10)

└─$ gcc --version
gcc (Debian 16.2.0-1) 16.2.0
RISC-V64:
1
2
3
4
5
└─$ riscv64-linux-gnu-gcc --version
riscv64-linux-gnu-gcc (Debian 16.2.0-2) 16.2.0

└─$ qemu-riscv64 --version
qemu-riscv64 version 11.1.1 (Debian 1:11.1.1+ds-1)